Last updated: 2026-09-20
Rewrite the layer, do not drop it in
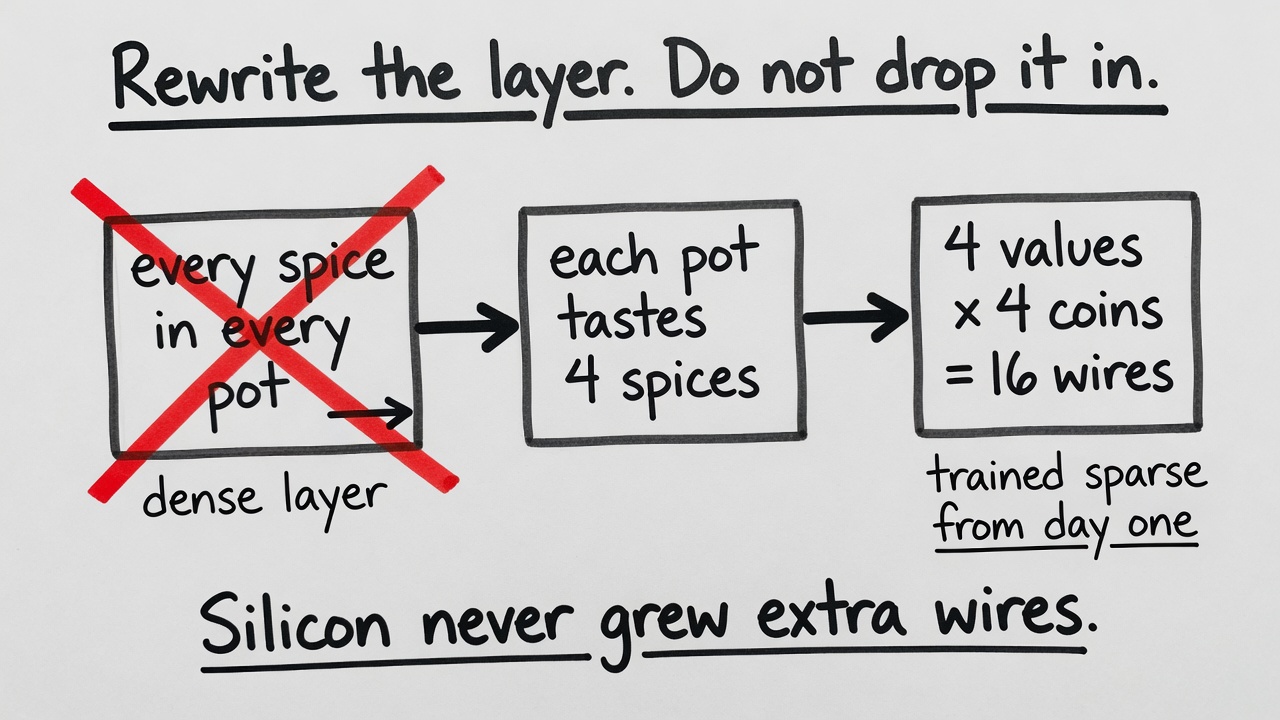
The old recipe says stir every spice into every pot. The new recipe says each pot only tastes four nearby spices, because that is how many values you can encode on sixteen neighbor wires once each value is a small bundle of coins.
The model is trained from the start with that fixed handful of connections, not pruned later. As the network gets wider, the percentage of unused possible connections goes toward one hundred. The silicon never grew extra wires.
Z1T is Extropic’s first family of transformer-like models rewritten so most of the work can live on that sparse, noisy chip, with a conventional companion doing the leftovers. Matching a small GPT-2’s quality took about ten times more training flops. The energy story still pencils out because the operations that land on Z1 are estimated at hundreds to thousands of times cheaper than the dense-machine equivalents.
Dense arithmetic still wins per training flop. That is not the bill a night desk pays after a peak lock. The bill is energy per next word, in a leftover closet.
A pruned dense model is still a city map taped onto a street. The street does not grow extra wires.