Last updated: 2026-09-20
Read the prompt on a dense machine; emit on the hybrid
Speed, under a conservative serial path: about 59 microseconds per token (~17,000 tokens per second) versus a measured H100 at batch one of 702 microseconds (eager) or 102 microseconds (compiled). That GPU comparison is a small model on a huge chip, so launch overhead inflates the GPU’s time. Batch the GPU and it looks much better.
Extropic’s own advice: use the hybrid for decode (emitting tokens one by one). Prefill (reading the prompt) still belongs on a GPU for now.
That split is the honest 2026 job. The radio log is already in. The night board needs the next line, then the next. That is decode. Cramming the whole prompt through the sparse street is not what the energy model was built for.
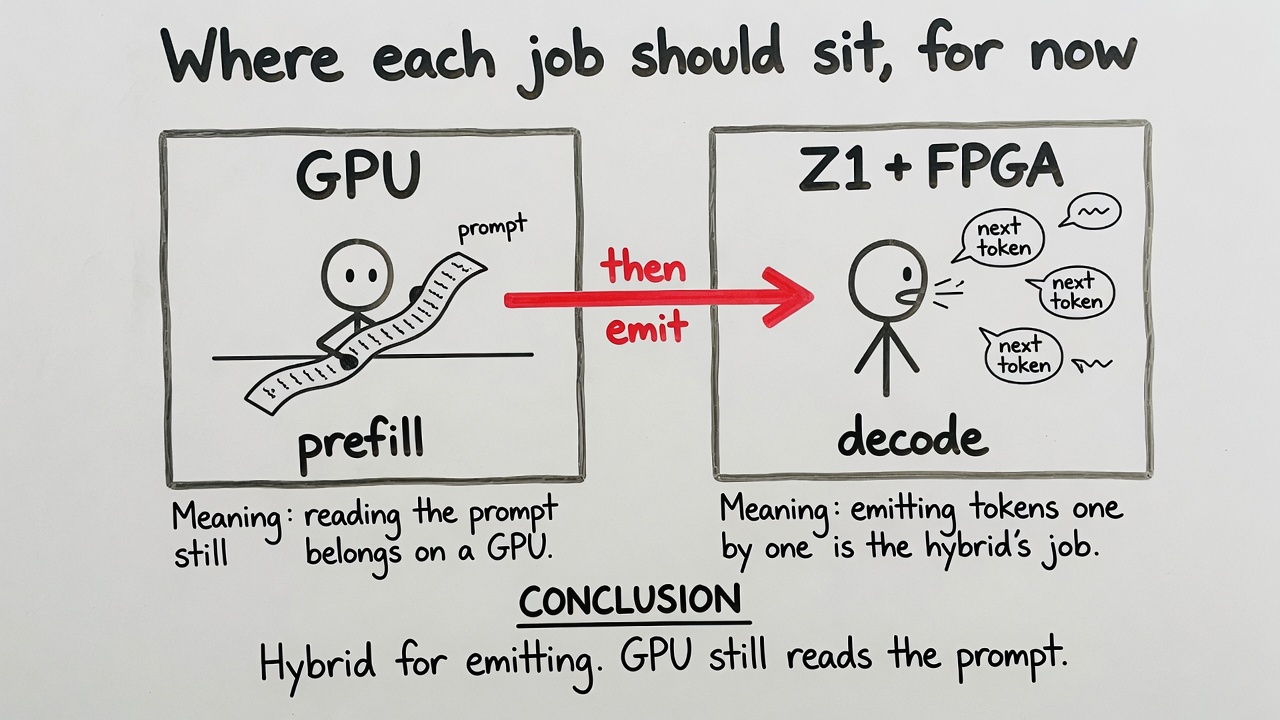
A night desk that tries to make the cheap chip do both jobs will spend the companion’s energy on the wrong half of the line.