Research · Call · log · HITL
API & audit trail
Last updated: 2026-09-16
How you call it
❓ What is the HTTP surface, and what does a request look like?
POST https://api.typesafe.ai/v1/systemone
Authorization: Bearer <API_KEY>
Content-Type: application/json
Top-level body: state (string, object, or array), model (docs say use "jev-latest"), questions (a map of ids you choose to question objects).[10] Question ids are not sent to the underlying model; they only key the response.[10]
Python SDK: pip install typesafe-sdk / uv add typesafe-sdk; TypeSafeClient().system_one(state=..., questions={...}) with Choice, Score, Noul helpers. Default model is jev-latest. Env var TYPESAFE_API_KEY.[11]
There is also a Playground at console.typesafe.ai/playground and an agent skill install (npx skills add typesafe-ai/skills --skill typesafe-ai, or Claude Code plugin).[11]
This is not OpenAI Chat Completions. You cannot point an existing OpenAI-compatible client at a new base URL and get Jev. A Python adapter repo exists for wrapping other models into the same question/answer shape, which is how TypeSafe runs LLM baselines on its evals.[33][1]
Decomposition is the product
❓ Why do the docs keep telling you to break the question up?
System One is specified as a gut-check: “the kind of judgment a highly knowledgeable person could make in a few seconds given the right context.” If the thing you want would take extended reasoning or mixes independent factors, the docs say: split it, ask each factor, combine in code.[6][41]
That is also how TypeSafe wants you to beat agents on reliability. Their “how to build” page contrasts three architectures:[41]
- Traditional code — primitives you trust, composed.
- An agent — a model chooses the next step; works when a person is watching.
- AI-powered software — code owns control flow and side effects; System One is inserted only at the semantic judgments.
Jev is sold for (3), not (2). A coding agent that calls Jev as a gate (see pi-jev below) is still an agent; Jev is the judge inside it, not the loop.
Where it sits in an agentic stack
❓ Is Jev a model, a tool, a skill, or a harness?
In the terms this workspace already uses:
| Layer | What it is | Jev’s relationship |
|---|---|---|
| Model | Weights + inference | Jev is this layer, with a closed output type |
| Tools | Side-effecting APIs the loop may call | Jev is a tool from the harness’s point of view (jev_ask); it does not have tools |
| Skills | Playbooks / procedures inside the harness | TypeSafe publishes an agent skill so other coding agents know the API shape[11] |
| Harness | The loop that calls models and tools | Not Jev. Hermes, Codex, Claude Code, Pi, etc. |
| HITL | Human in the loop | Confidence bands are how Jev is supposed to create a HITL boundary in code[9] |
So: Jev is a model that is useful as a tool. It is not a harness. It does not replace structured tool-calling; it is a thing you might call before a tool runs.
Community example: y0usaf/pi-jev uses Jev as a decision layer on the Pi coding agent — a gate on bash / write / edit (e.g. noul “is this destructive?” at 0.90), an output judge on bash stdout, and a jev_ask tool for the model to request typed judgments.[28] That is exactly the “smart if-statement” the manifesto describes.[3]
Data, residency, enterprise SKU
❓ What is public about logs, region, and contracts?
Not in the docs index reviewed on 16 September 2026: residency table, ZDR, training-on-your-data policy, DPA, SOC 2, VPC. Launch copy and DCVC place the company and the current service in the US (West Coast latency caveat).[1][15] A federal credit union or other FRFI that put Jev on a live path would still have to register the use under its model-risk program; the closed US API does not change that. See 09-vendor-risk.
Automated decisions and an explainable audit trail
❓ Can Jev automate a decision and still leave an explainable audit trail?
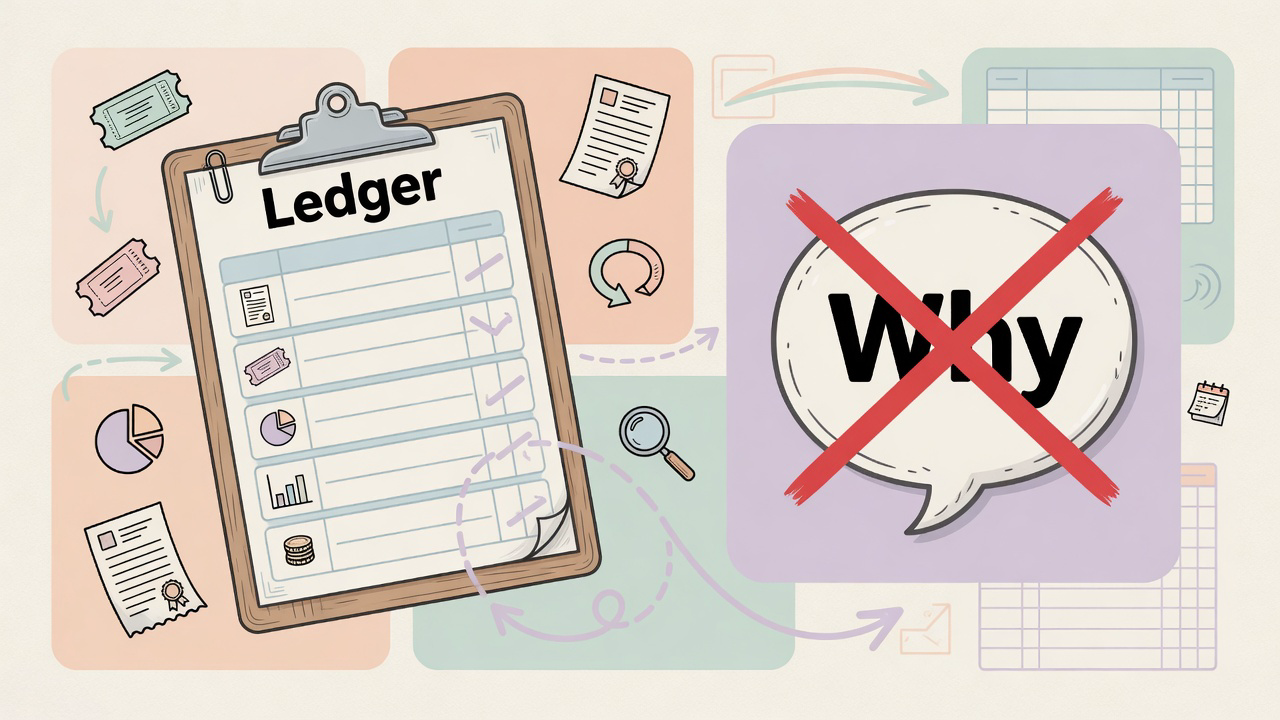
Automation, yes. The API is built for code to act: state plus typed questions in; Choice / Score / Noul plus probabilities out; the caller’s program branches. TypeSafe’s documented pattern is three bands — act, confirm, escalate — with thresholds in your code.[9][41] Noul has no separate confidence; the 0–1 value is the signal.[31] That is a human-in-the-loop gate, not a chatbot that narrates a plan. The leftover error is wrong-but-typed: calibration does not guarantee a single answer.[7]
A natural-language rationale, no. Docs: System One models “do not write replies, produce code, or generate explanations of their reasoning.”[7] A HN comment from an account identifying as a TypeSafe employee said to put reasoning in code.[38]
What you can persist, because it is already structured:
| Field logged | What a later reviewer can see |
|---|---|
state |
The exact document judged |
Question instructions + criteria / options |
The policy you asked |
choice / score / noul |
The decision |
Full probabilities |
Alternatives not picked |
confidence (Choice/Score only) |
How peaked the distribution was |
model |
Which SKU answered |
| Your action + threshold | Why the program paid, held, or paged a human |
That is an inspectable decision record, not a rationale. Confidence 1.0 means the mass sat on one option; TypeSafe says that describes the answer, not that it is correct.
A fuller trail is assembled in code: split the judgment, compose scores, log the composition (“Noul duplicate-charge 0.97; Choice returns 0.60 / billing 0.38, confidence 0.39 → hold”). TypeSafe’s citation-check cookbook uses Jev to judge an LLM’s citations, not to author the explanation. There is no “why” string, no chain-of-thought, and no published vendor audit log; the trail is what the caller stores. jev-latest can move under a tuned threshold unless pinned.[10]
❓ If an auditor needs “why” in sentences, where does that text come from?
From the questions, the rules, and a human — not from Jev.